What Is Kruskal’s Algorithm in Data Structure?
Kruskal’s Algorithm is a greedy algorithm used to find the Minimum Spanning Tree (MST) of a connected, weighted, and undirected graph.
It works by selecting edges in increasing order of their weights (costs). At each step, it chooses the smallest available edge that does not form a cycle with the already selected edges.
The process continues until all vertices are connected and exactly V-1 edges have been selected, where V represents the total number of vertices.
Kruskal’s algorithm is commonly used in network design, road construction, electrical distribution systems, and other problems where all locations need to be connected with minimum total cost.
Example: Suppose five cities need to be connected using communication cables. Each possible connection has a different installation cost. Kruskal’s algorithm helps select connections that connect all five cities with the minimum total cost without creating unnecessary cycles.
How Kruskal’s algorithm works
Kruskal’s algorithm is a greedy method to find a minimum spanning tree. A greedy algorithm always picks the next edge that looks best at the moment, and this leads to the overall best solution. We start by adding the edge with the smallest weight, then keep adding the next smallest edges one by one. While doing this, we make sure all vertices are connected and no cycles are formed, so the minimum spanning tree rules are followed.
Properties of Minimum spanning tree
- Connects All Vertices – An MST includes all the vertices of the graph, ensuring that every node is reachable from any other node.
- No Cycles – Since an MST is a tree, it does not have any cycles or loops. This ensures that there is exactly one path between any two vertices.
- Minimum Total Weight – The sum of the weights of all edges in the MST is the smallest possible among all spanning trees of the graph. This makes it optimal in terms of cost, distance, or any weight assigned to edges.
- Unique or Multiple MSTs – If all edge weights are distinct, the MST is unique. If some edges have the same weight, there can be multiple different MSTs with the same total weight.
- Exactly V-1 Edges – For a graph with V vertices, an MST always has V – 1 edges. Adding more would create a cycle, and fewer edges would not connect all vertices.
- Subset of Original Graph – Every edge in the MST is chosen from the edges present in the original graph, and no new edges are introduced.
The steps for implementing Kruskal’s algorithm are as follows
Step 1: Remove all loops and parallel edges.
Step 2: Sort all the edges in non-decreasing order of their weight.
Step 3: Pick the least weightage edge and include this edge if it does not form a cycle. Else, discard it.
Step 4: Repeat step 2 until we get a minimum spanning tree.
Example to understand Kruskal’s algorithm
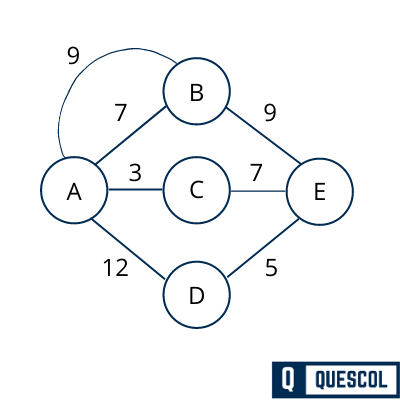
Step 1 – Remove all loops and Parallel Edges
After removing parallel edge from the graph, graph will look like below.
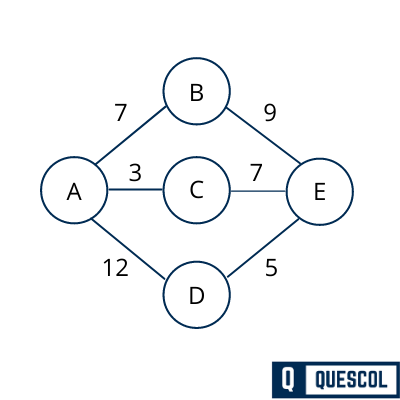
Step 2 – Sort all the edges in non-decreasing order of their weight
AC – 3, DE – 5, AB – 7, BE – 9, CE – 7, AD – 12
Step 3 – Pick the least weightage edge and include this edge
We will add edges to the graph beginning with the one that has the least weight. We will also keep checking that this edge does not form any cycle. If a cycle is created by adding an edge or any other property that violates the spanning-tree property, then we will not include the edge in the graph.
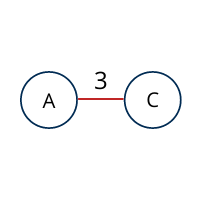
The least cost is 3 and the edge involved is AC. We add it. Adding it does not violate spanning-tree properties, so we continue to our next edge selection.
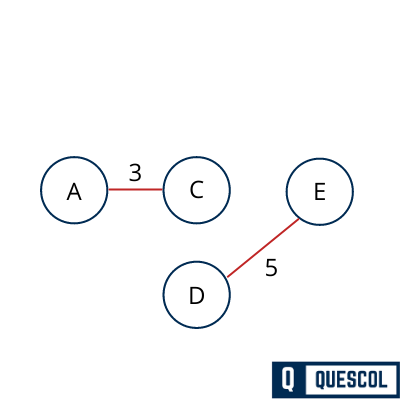
Next we will select Edge DE which have least weight 5 and not violating spanning tree properties.
Next we will select Edge AB which have least weight 7 and not violating spanning tree properties.
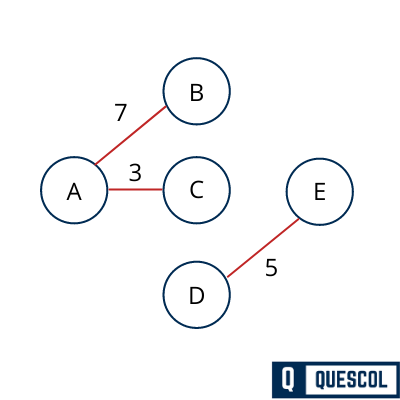
Next we will select Edge CE which have least weight 7 and not violating spanning tree properties.
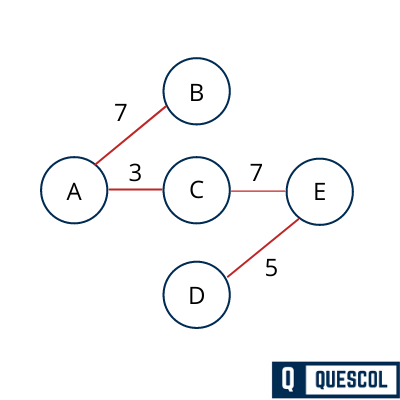
So Create Minimum spanning tree using Kruskal’s algorithm will look like above.
Program to implement Kruskal’s algorithm
#include <stdio.h>
#include <stdlib.h>
struct Edge {
    int u, v, weight;
};
// Comparison function to sort edges by weight
int compare(const void* a, const void* b) {
    return ((struct Edge*)a)->weight - ((struct Edge*)b)->weight;
}
// Find function for union-find
int find(int parent[], int i) {
    if (parent[i] == i)
        return i;
    return parent[i] = find(parent, parent[i]);
}
// Union function for union-find
void unionSets(int parent[], int rank[], int x, int y) {
    int xroot = find(parent, x);
    int yroot = find(parent, y);
    if (rank[xroot] < rank[yroot])
        parent[xroot] = yroot;
    else if (rank[xroot] > rank[yroot])
        parent[yroot] = xroot;
    else {
        parent[yroot] = xroot;
        rank[xroot]++;
    }
}
void kruskal(struct Edge edges[], int V, int E) {
    // Sort edges by weight
    qsort(edges, E, sizeof(struct Edge), compare);
    int parent[V];
    int rank[V];
    for (int i = 0; i < V; i++) {
        parent[i] = i;
        rank[i] = 0;
    }
    printf("Edges in the Minimum Spanning Tree:\n");
    int count = 0;
    for (int i = 0; i < E && count < V - 1; i++) {
        int u = edges[i].u;
        int v = edges[i].v;
        int setU = find(parent, u);
        int setV = find(parent, v);
        if (setU != setV) {
            printf("%d -- %d == %d\n", u, v, edges[i].weight);
            unionSets(parent, rank, setU, setV);
            count++;
        }
    }
}
int main() {
    int V = 4; // Number of vertices
    int E = 5; // Number of edges
    struct Edge edges[] = {
        {0, 1, 10},
        {0, 2, 6},
        {0, 3, 5},
        {1, 3, 15},
        {2, 3, 4}
    };
    kruskal(edges, V, E);
    return 0;
}
Output
Edges in the Minimum Spanning Tree:
2 -- 3 == 4
0 -- 3 == 5
0 -- 2 == 6
Explanation of Code
1.Struct Edge
struct Edge {
    int u, v, weight;
};
The struct Edge defines an edge in the graph. Each edge has three parts: u which is the starting vertex, v which is the ending vertex, and weight which is the cost of traveling or connecting between u and v. This struct helps store all the graph edges in a single array.
2.Compare Function
int compare(const void* a, const void* b) {
    return ((struct Edge*)a)->weight - ((struct Edge*)b)->weight;
}
The compare function is used with qsort to sort all edges by their weight in ascending order. Sorting is important because Kruskal’s algorithm always starts with the edge that has the smallest weight to construct the Minimum Spanning Tree efficiently.
3.Find Function
int find(int parent[], int i) {
    if (parent[i] == i)
        return i;
    return parent[i] = find(parent, parent[i]);
}
The find function implements union-find with path compression. For a given vertex, it returns the root parent of its set. Path compression makes future searches faster by directly connecting nodes to their root parent. This function is crucial to check whether adding an edge will form a cycle in the MST.
4.Union Function
void unionSets(int parent[], int rank[], int x, int y) {
    int xroot = find(parent, x);
    int yroot = find(parent, y);
    if (rank[xroot] < rank[yroot])
        parent[xroot] = yroot;
    else if (rank[xroot] > rank[yroot])
        parent[yroot] = xroot;
    else {
        parent[yroot] = xroot;
        rank[xroot]++;
    }
}
The unionSets function merges two sets (trees) into one. It uses union by rank, meaning the tree with smaller rank is attached under the tree with larger rank to keep the structure shallow. If both sets have the same rank, one becomes the parent and its rank is incremented. This helps maintain efficiency and ensures no cycles are formed while adding edges to the MST.
5.Kruskal Function
void kruskal(struct Edge edges[], int V, int E) {
    qsort(edges, E, sizeof(struct Edge), compare);
    int parent[V];
    int rank[V];
    for (int i = 0; i < V; i++) {
        parent[i] = i;
        rank[i] = 0;
    }
    printf("Edges in the Minimum Spanning Tree:\n");
    int count = 0;
    for (int i = 0; i < E && count < V - 1; i++) {
        int u = edges[i].u;
        int v = edges[i].v;
        int setU = find(parent, u);
        int setV = find(parent, v);
        if (setU != setV) {
            printf("%d -- %d == %d\n", u, v, edges[i].weight);
            unionSets(parent, rank, setU, setV);
            count++;
        }
    }
}
The kruskal function is where the MST is actually built. First, it sorts all edges by weight. Then, it initializes parent and rank arrays for all vertices for union-find. The function loops through each edge and checks if its two vertices belong to different sets using find. If they do, the edge is added to the MST and the sets are united using unionSets. This continues until the MST has exactly V-1 edges. Every selected edge is printed as part of the MST.
6. Main Function
int main() {
    int V = 4;
    int E = 5;
    struct Edge edges[] = {
        {0, 1, 10},
        {0, 2, 6},
        {0, 3, 5},
        {1, 3, 15},
        {2, 3, 4}
    };
    kruskal(edges, V, E);
    return 0;
}
The main function defines the graph by specifying the number of vertices V and edges E. It creates an array of Edge structs representing all the edges in the graph. Finally, it calls the kruskal function to compute and display the Minimum Spanning Tree.
Time & Space Complexity of Kruskal’s algorithm
| Operation | Time Complexity |
|---|---|
Sorting edges (qsort) | O(E log E) |
| Union-Find operations | O(E α(V)) |
| MST Construction Loop | O(E) |
| Overall | O(E log E) |
| Component | Space Complexity |
|---|---|
| Edges array | O(E) |
| Parent array | O(V) |
| Rank array | O(V) |
| Temporary variables | O(1) |
| Total | O(V + E) |
Applications of Kruskal’s Algorithm
Kruskal’s algorithm is useful in problems where multiple locations or components need to be connected with minimum total cost.
Some important applications include:
1. Computer Network Design
Kruskal’s algorithm helps design computer networks by selecting connections between different locations while minimizing the total cable installation cost.
For example, it can be used to connect multiple office buildings using the minimum total length of network cables.
2. Road and Railway Construction
It can help identify a minimum-cost network of roads or railway connections that connects all required cities or stations.
3. Electrical Distribution Networks
Kruskal’s algorithm can help determine efficient connections between power distribution points while minimizing the total cost of connecting the network.
4. Water Pipeline Networks
It can be used to design pipeline connections between different areas while minimizing the total installation cost.
5. Data Clustering
Minimum spanning trees can be used in clustering techniques to analyze relationships and distances between data points. Removing selected high-weight edges can help separate the data into clusters.
6. Circuit Design
It can help identify low-cost connections between components in certain circuit and wiring optimization problems.